Token Optimization Assistant
Token Optimization Assistant
Showcase
Description
Diagnose the token consumption of the current session, provide optimization suggestions that can be executed immediately, helping users improve conversation efficiency and response speed.
Recommended by
nene@YouMind
Why we love this skill
Frustrated by slow AI and fast token usage? This assistant pinpoints conversation issues, analyzes token sources, and offers 3-5 prioritized suggestions—from quick cleanup to long-term habits—boosting AI efficiency and saving resources for smoother, more economical conversations.
Related Skills
View all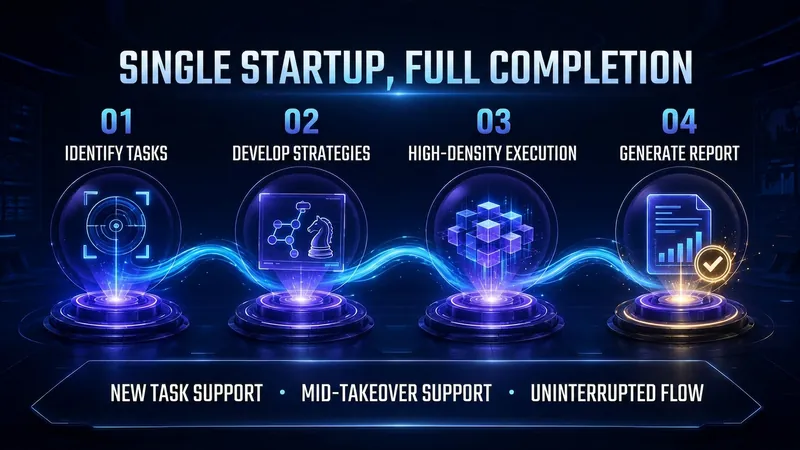
Token Actuary
Have you ever calculated how much you pay each month for AI's "fluff"? "Okay, let me help you..." "First, let's review your question..." "In summary, here's what we covered..." You don't even glance at these, but every word eats your tokens. 💸 I built a Skill called "Token Actuary" to fix this: ✅ Automatically identifies task type and applies token-saving strategies ✅ Cuts redundancy without cutting depth—quality stays 100% ✅ Generates an itemized bill: "This time saved 40%+", clear and transparent For heavy AI users, install it once and save the cost of a few bubble teas. A fact most overlook: a significant portion of what you pay for AI isn't for the "answer" — it's for "process language": opening pleasantries, restating the question, transitional filler, closing summaries. These add no value, but every token costs you. I've packaged the entire methodology of information density optimization into a Skill: "Token Actuary". Its logic is straightforward: after identifying the task type, it automatically matches token-saving strategies, executes tasks with maximum information density, eliminates all redundancy, and enforces strict quality constraints so output doesn't degrade. After completion, it auto-generates a token breakdown report showing consumption per stage, savings vs. standard mode, and future optimization tips. Supports both launch-time activation and mid-task takeover—no configuration needed. If you're a heavy AI user—writer, researcher, bulk content creator, or pay-per-token API user—this Skill is essentially a "money-saving machine": install once, and every conversation compresses your costs. It's now available on the YouMind Skill Market. Search for "Token Actuary" to install.
Model Routing & Token Saver
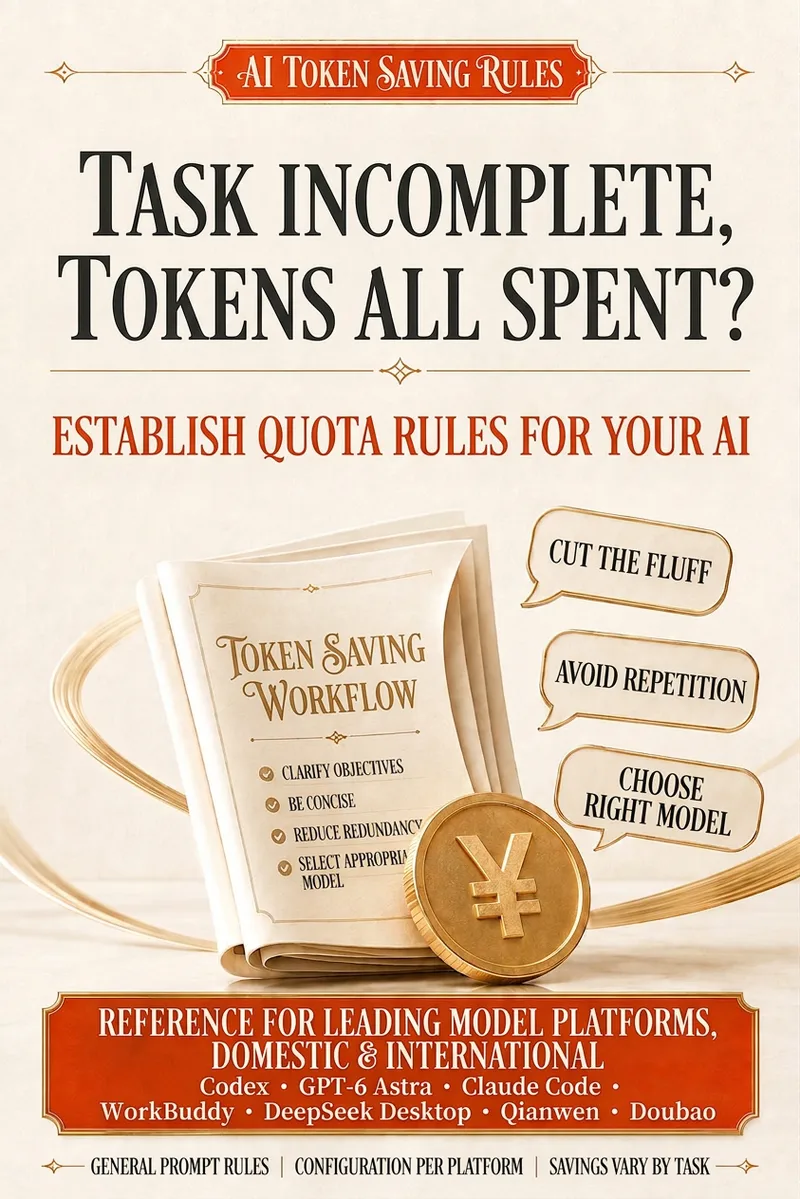
Based on task difficulty, content type, and project stage, it helps you choose a more suitable AI model and apply quota-saving rules to AI to reduce token usage. While keeping quota consumption under control, it supports programming, creative work, planning, design, and information analysis. Whether you need page components, API integrations, simple bug fixes, architecture design, complex logic, code reviews, or refactoring, it provides clear model recommendations and directly delivers the requested results. It is also well suited to everyday copywriting, titles and hooks, story-driven content, brand proposals, marketing plans, PPT outlines, visual concepts, market trends, competitor analysis, and data interpretation. Simple, batch, and formatting tasks are prioritized for greater quota efficiency. For major decisions, complex reasoning, or final polishing, it reminds you to invest in a more suitable model for quality. With continued use, it adjusts its recommendations based on your model preferences, output habits, project tech stack, key decisions, pending tasks, and known issues, reducing repetitive communication. For coding tasks, it focuses by default on the core changes and summarizes what was modified. For copywriting and proposal tasks, it first organizes the overall framework and then expands it as needed, making each conversation better aligned with your current project and working rhythm.
Token Smart Optimizer
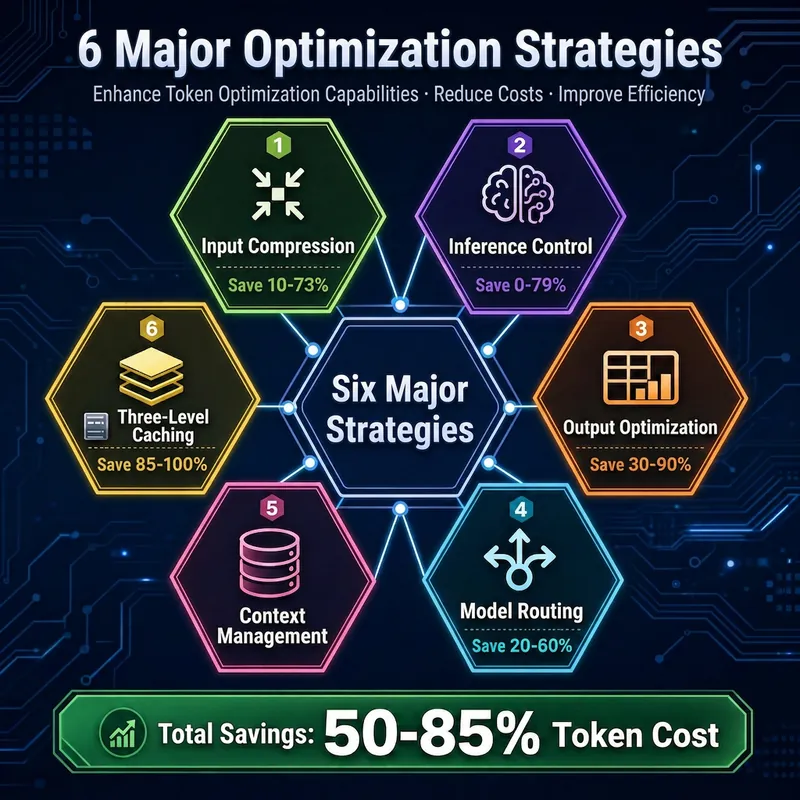
Smart detection · Silent optimization · Full YouMind coverage. Automatically detects optimization opportunities and silently applies strategies, supporting three entity types: Board, Chaos, and Elf. Based on actual YouMind model costs, intelligently routes to select the optimal model, achieving 50-85% token cost savings. After installation, integrate via Board Memory for near-automatic optimization, with first-run automatic setup guide.
Information
- Version
- v1
- Last updated
- Runtime credits
- Usage-based
- Models
- Auto